
In this part
Synthetic data is having a global moment.
Across artificial intelligence, machine learning, healthcare, financial services and software engineering, organizations are increasingly using artificially generated data to supplement real-world datasets, protect privacy, test systems and train models.
For Africa, however, the conversation is more complicated.
The continent does not simply face a shortage of AI-ready datasets. In many markets, important records remain fragmented across institutions, inconsistently digitized, difficult to access, expensive to obtain or legitimately restricted by privacy requirements.
That creates an uncomfortable paradox.
If a synthetic-data system depends heavily on abundant, representative real-world microdata, what happens when the very reason synthetic data is needed is that such data does not exist at sufficient scale?
And if poorly grounded synthetic data simply reproduces assumptions imported from somewhere else, have we solved Africa's data problem — or automated it?
These are valid concerns.
At STRIPED DONKEY, we believe they point toward a different architecture.
Not artificial survey respondents pretending to represent real Africans.
Not millions of plausible but disconnected rows.
And not synthetic data presented as a substitute for observed reality.
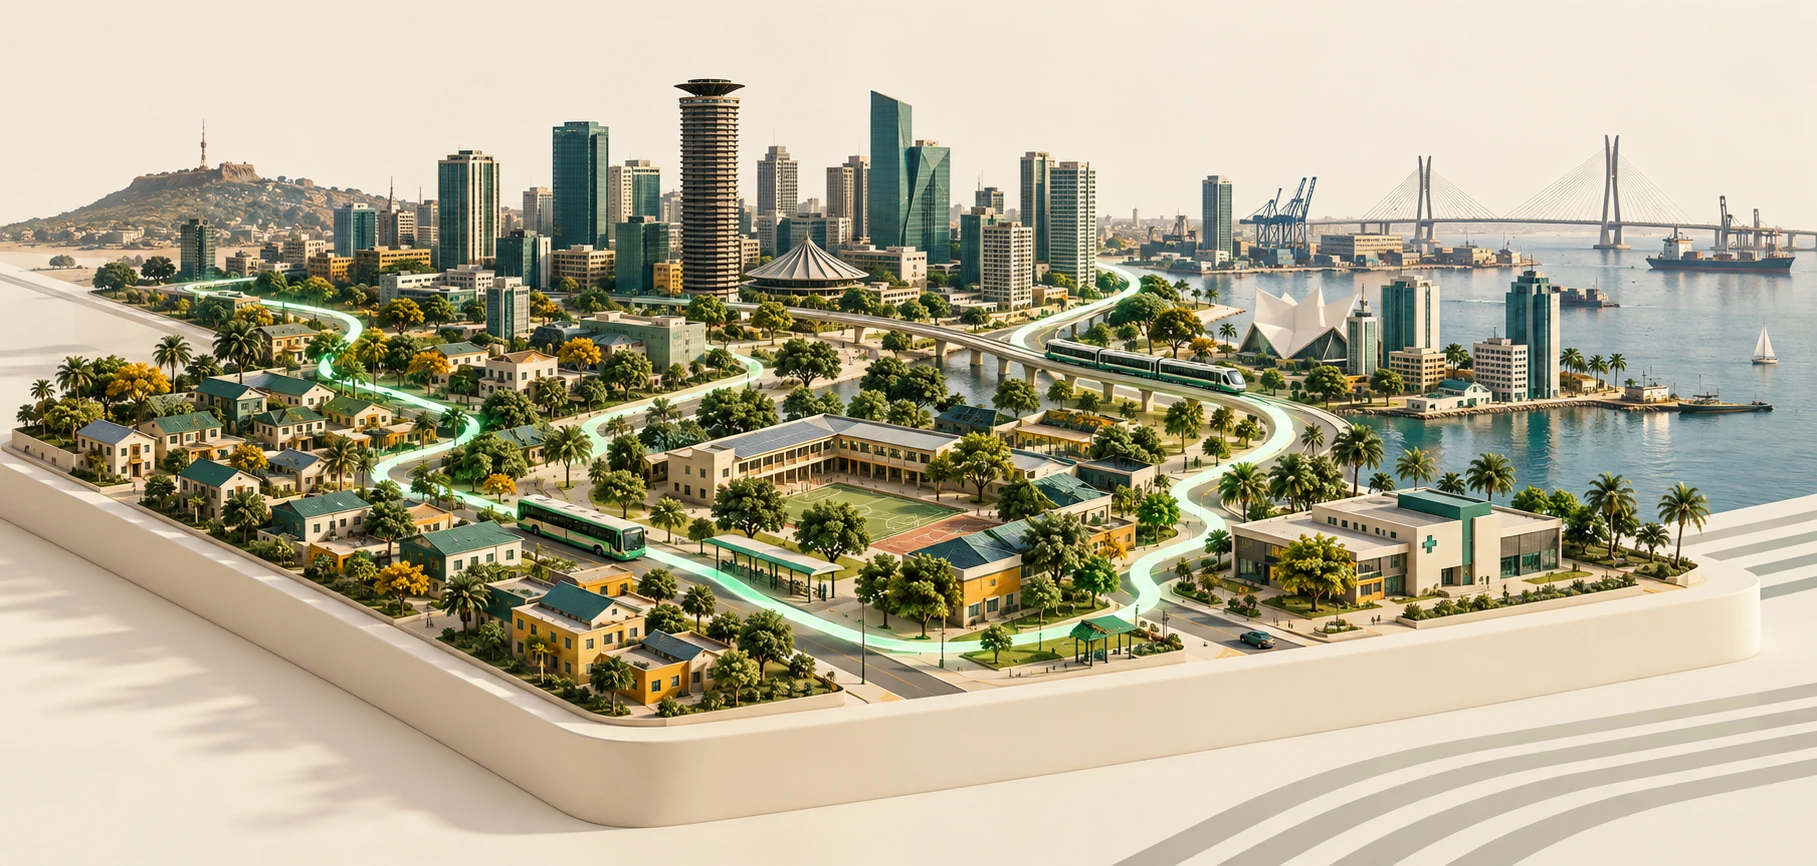
Instead, we are building Synthetic City Twins:
- persistent synthetic residents;
- households that exist through time;
- education histories that can precede employment;
- employment that can change;
- health events connected to broader life histories;
- and multiple domains linked to the same underlying synthetic population.
The technology behind this approach is the Fidelra City Twin Engine — FCTE.
Its central idea is simple:
One citizen. Many domains. Across time.
Africa's Data Problem Is Also a Connection Problem
Discussions about Africa's data gap usually focus on quantity.
Not enough health data.
Not enough employment data.
Not enough locally relevant training data.
Not enough longitudinal data.
But quantity is only part of the challenge.
The other problem is connection.
A health dataset may contain clinical encounters without employment history.
An employment dataset may contain occupations without educational pathways.
An education dataset may describe graduates without showing what happened to them afterward.
A transport dataset may record movement without household, economic or demographic context.
The datasets exist as islands.
Yet real cities do not work that way.
A person studies, enters the workforce, changes jobs, moves residence, joins a household, uses transport, becomes insured, visits a clinic, changes mobile providers, starts a business or experiences other life transitions.
Those events are connected because the person is connected.
For many AI, research and simulation problems, that continuity matters.
The question is therefore not simply:
How do we create more African data?
It is:
How do we create data in which relationships between people, households, institutions and events remain coherent through time?
That is the problem Synthetic City Twins are designed to explore.
One citizen. Many domains. Across time.
citizen
- Education
- Employment
- Health
- Insurance
- Household
- Transport
A Different Model of Synthetic Data
Synthetic data is not a single technology.
Some approaches learn the statistical distribution of an existing dataset and generate new records resembling it.
Others use simulation, probabilistic models, rules, generative AI or combinations of several techniques.
FCTE starts from a different premise.
The objective is not to reconstruct individual real people.
It is to create a fully synthetic population whose chronology, relationships and aggregate behaviour can be tested against explicit evidence, constraints and assumptions.
The architecture can be summarized as:
From evidence to connected data
The distinction is important.
The claim is not:
“This synthetic resident represents a particular real resident.”
The relevant question is:
“Does this synthetic population behave coherently enough, and align closely enough with available evidence, for the intended analytical or engineering use?”
Those are fundamentally different standards.
From Rows to Lives
Consider employment.
A conventional employment dataset might contain:
- Age
- Education
- Occupation
- Income
- Employment Status
Such data can be useful.
But it says little about how someone arrived at that state.
A longitudinal city model can ask different questions:
- When did education end?
- When did employment begin?
- Was there a promotion?
- Was employment terminated?
- Did the resident later enter self-employment?
- Which qualifications existed at the time of an employment event?
- What happened next?
The same principle applies to healthcare.
Rather than generating an isolated diagnosis row, a connected model can retain the synthetic resident's earlier healthcare activity, household context, employment state, insurance position and later outcomes.
That changes the kinds of analytical questions the data can support.
Instead of asking only:
What percentage of this table has characteristic X?
we can begin asking:
What happened before X?
What happened afterward?
Which earlier conditions were associated with the transition?
Can a model trained on an earlier synthetic period predict a later synthetic outcome without leaking future information?
That is the difference between generating records and constructing a synthetic longitudinal environment.
Nairobi and Lagos: Building at City Scale
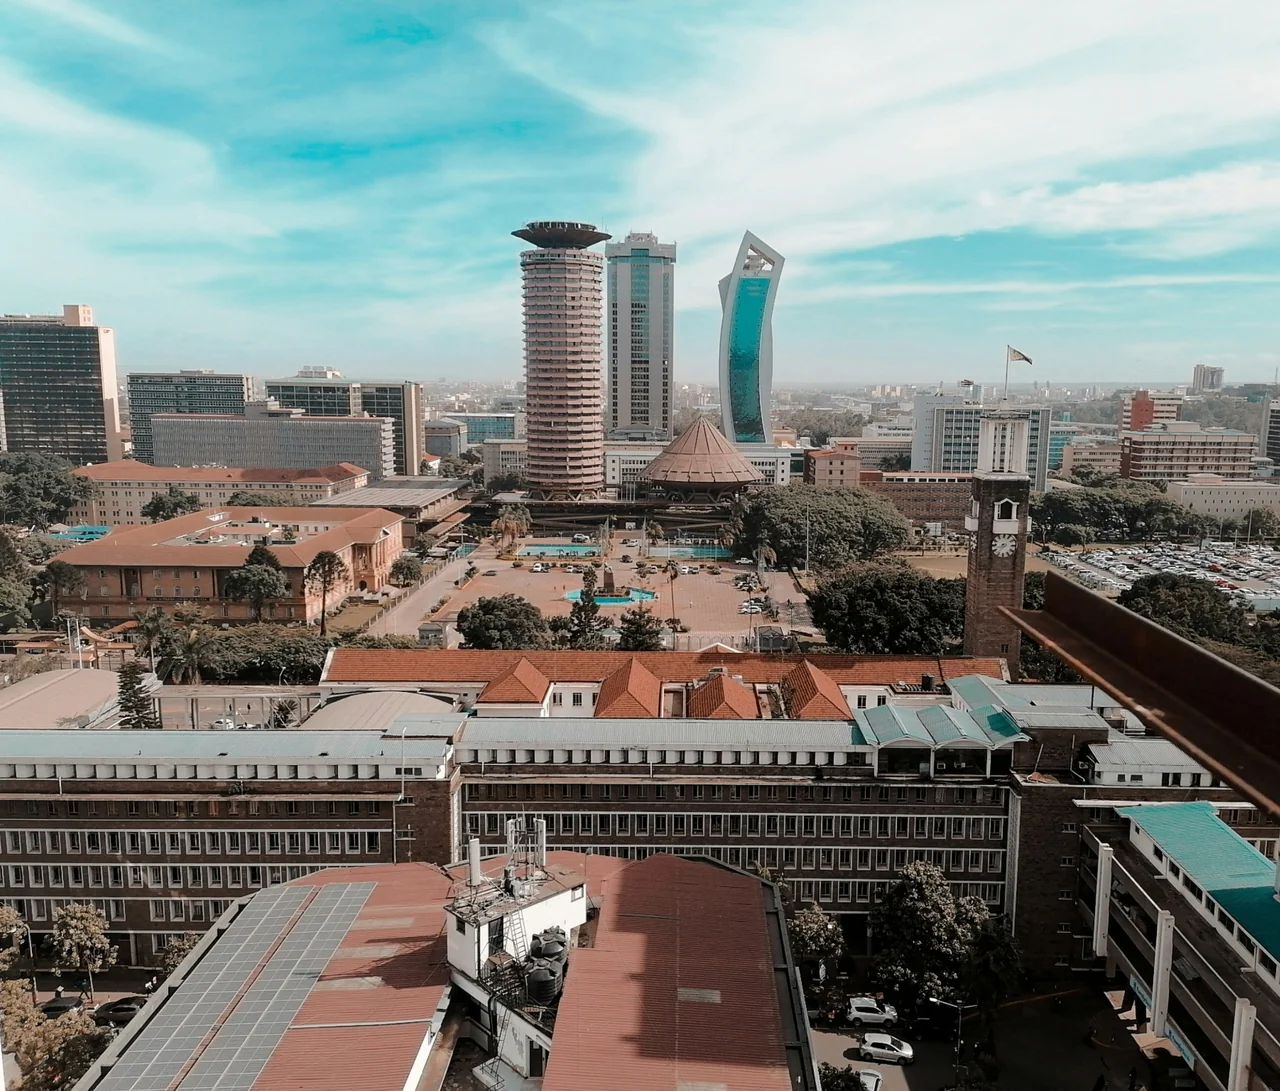
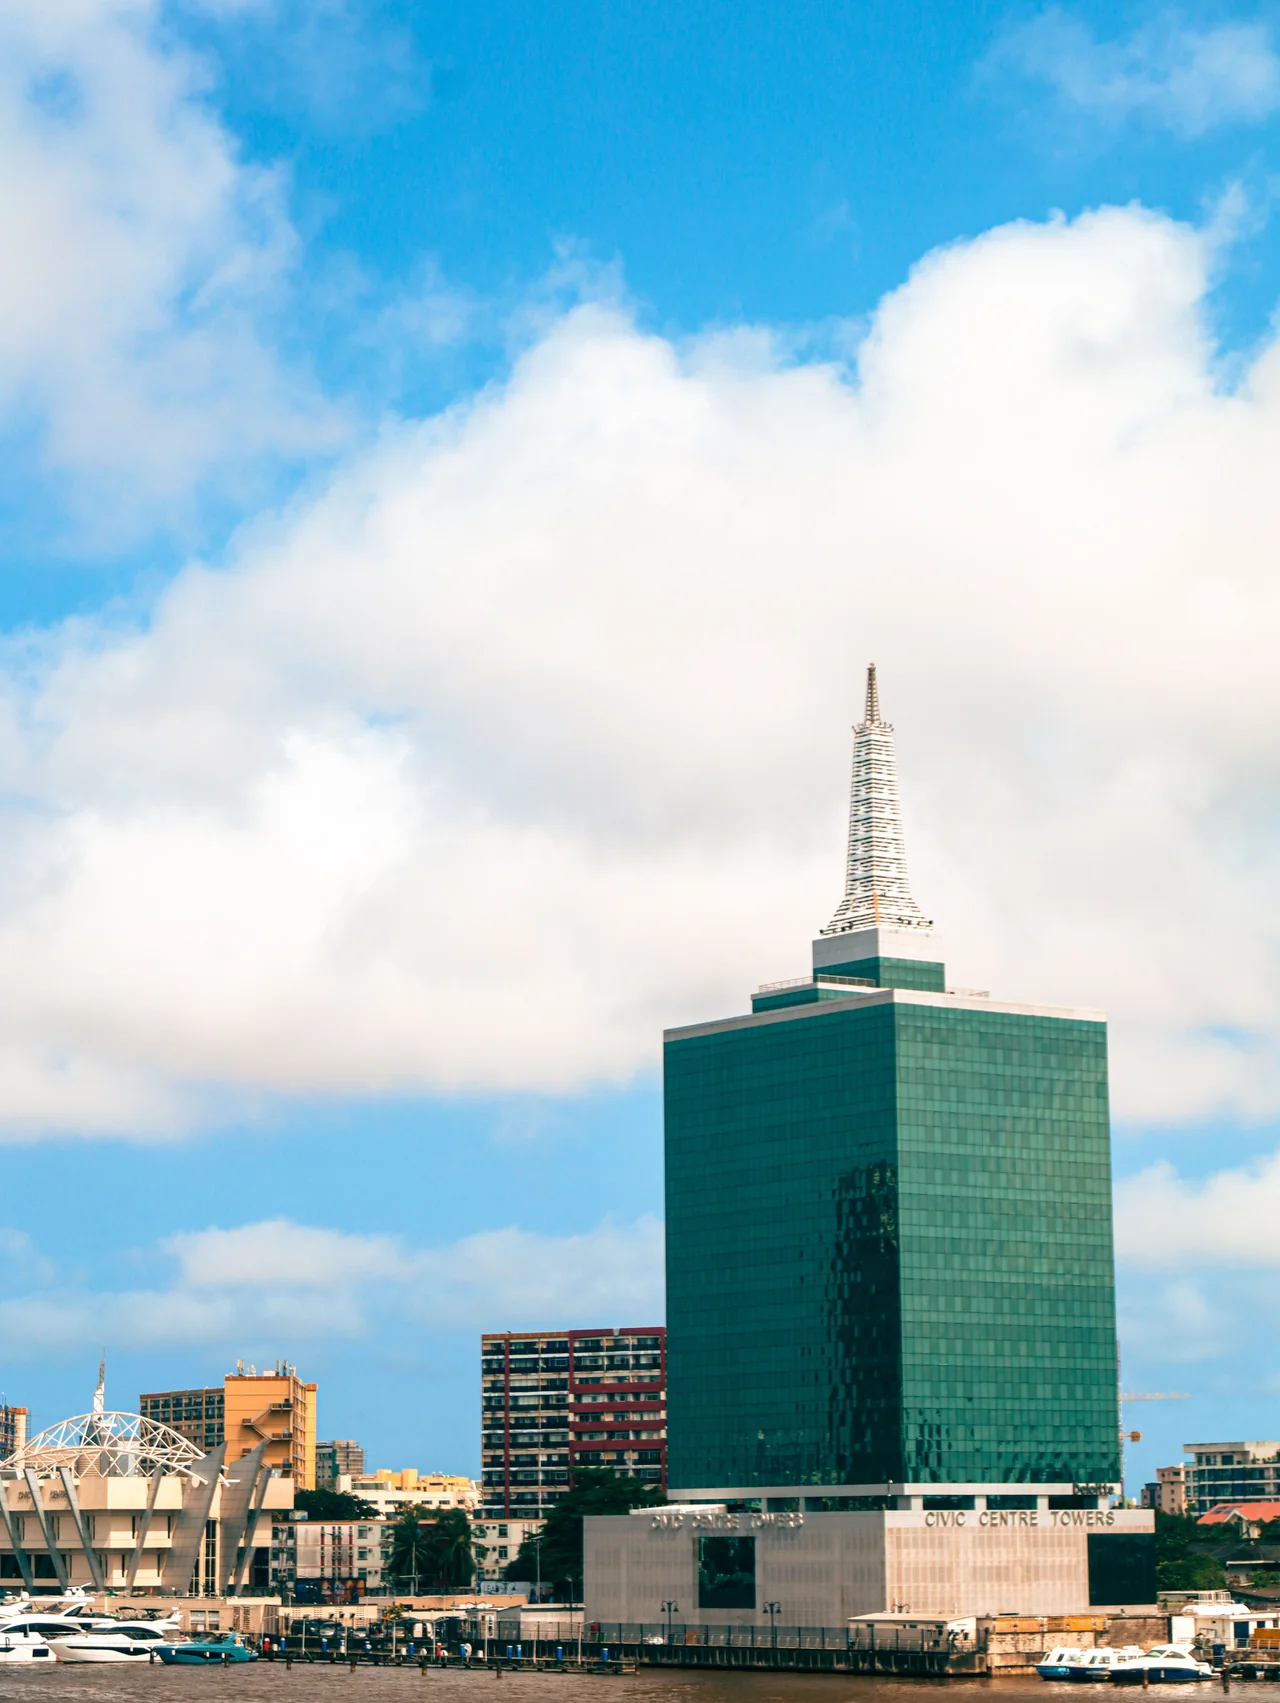
STRIPED DONKEY's first Synthetic City Twins are Nairobi, Kenya and Lagos, Nigeria.
The current city models contain approximately:
- 5.08 million synthetic Nairobi residents
- 26.39 million synthetic Lagos residents
Those numbers require an important qualification.
They are synthetic model population counts.
They are not official census estimates and should never be interpreted as direct measurements of the real cities.
That separation is deliberate.
The objective is not to blur simulation and observation.
It is to build sufficiently large synthetic populations for machine-learning development, longitudinal research, software engineering and controlled experimentation while maintaining a clear distinction between:
what was observed
and
what was simulated.
That boundary is essential to trust.
Time Changes Everything
A city is not a snapshot.
Neither should a city twin be.
The current FCTE architecture extends synthetic histories back to 1940, allowing later states to emerge within a historical sequence rather than appearing as isolated present-day records.
Why does this matter?
Because many outcomes are path-dependent.
Education systems change.
Industries change.
Households evolve.
Transport networks expand.
Technology adoption changes.
Healthcare systems develop.
Employment pathways shift.
A synthetic resident born decades ago should not simply inherit the same institutional environment as someone born recently.
Chronology therefore becomes a constraint.
A university completion must occur after enrollment.
Employment should not begin before the resident is eligible for it.
A promotion belongs inside a valid employment episode.
A person's age at an event must agree with their date of birth.
A historical machine-learning feature must not contain information that would only have become available later.
These rules sound obvious.
At millions of residents and potentially billions of connected records, maintaining them consistently becomes a serious engineering problem.